Search  for anything...

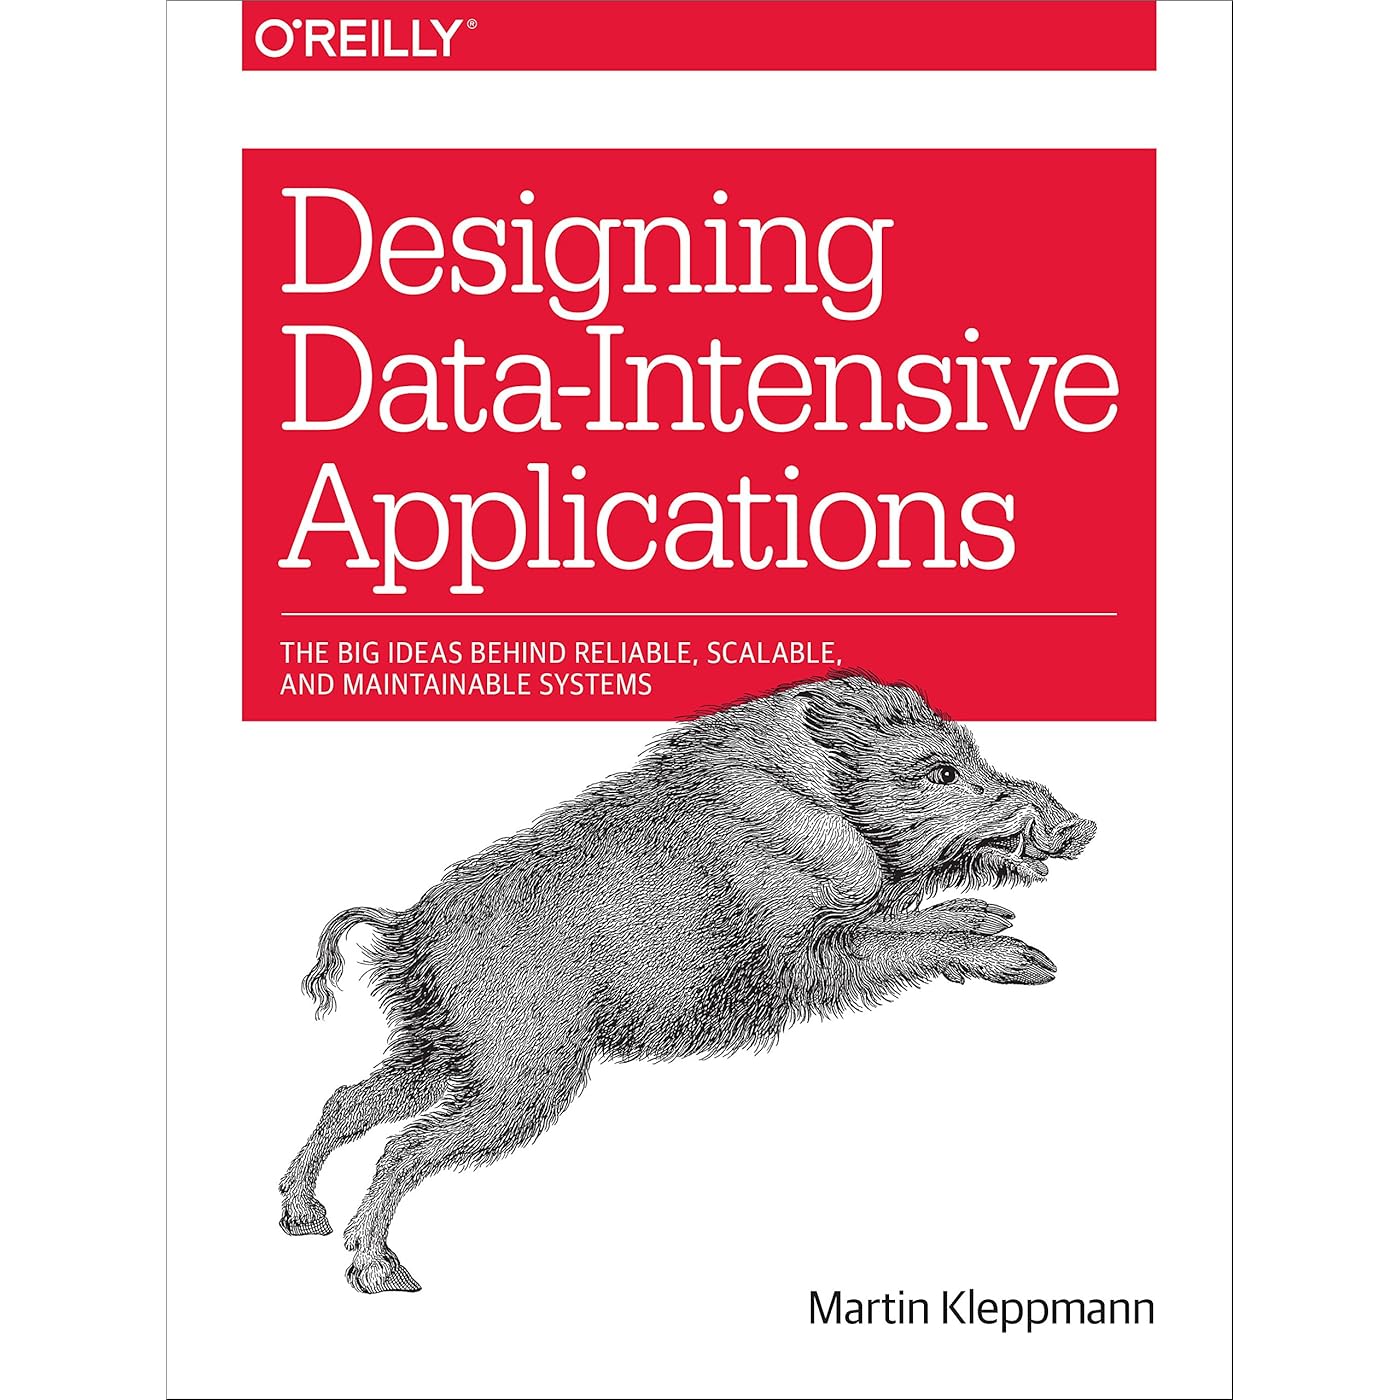
Designing Data-Intensive Applications: The Big Ideas Behind Reliable, Scalable, and Maintainable Systems
  • Based on 5,596 reviews
Condition: Used - Very Good
Checking for the best price...

Buy Now, Pay Later


As low as $11.99 / mo
  • – 6-month term
  • – No impact on credit to apply
  • – Instant approval decision
  • – Secure and straightforward checkout

Ready to go? Add this product to your cart and select a plan during checkout.

Payment plans are offered through our trusted finance partners Klarna, Affirm, Afterpay, Zip, Apple Pay, and Google Pay. No-credit-needed leasing options through Acima may also be available at checkout.

Learn more about financing & leasing here.

Selected Option

Free shipping on this product

This item is eligible for return within 30 days of receipt

To qualify for a full refund, items must be returned in their original, unused condition. If an item is returned in a used, damaged, or materially different state, you may be granted a partial refund.

To initiate a return, please visit our Returns Center.

View our full returns policy here.


Availability: Only 3 left in stock, order soon!
Fulfilled by World of Books (previously glenthebookseller)

Arrives Tuesday, Oct 13
Order within 18 hours and 25 minutes
Available payment plans shown during checkout

Protection Plan Protect Your Purchase
Checking for protection plans...

Format: Paperback, Illustrated


Description

Data is at the center of many challenges in system design today. Difficult issues need to be figured out, such as scalability, consistency, reliability, efficiency, and maintainability. In addition, we have an overwhelming variety of tools, including relational databases, NoSQL datastores, stream or batch processors, and message brokers. What are the right choices for your application? How do you make sense of all these buzzwords?In this practical and comprehensive guide, author Martin Kleppmann helps you navigate this diverse landscape by examining the pros and cons of various technologies for processing and storing data. Software keeps changing, but the fundamental principles remain the same. With this book, software engineers and architects will learn how to apply those ideas in practice, and how to make full use of data in modern applications.Peer under the hood of the systems you already use, and learn how to use and operate them more effectivelyMake informed decisions by identifying the strengths and weaknesses of different toolsNavigate the trade-offs around consistency, scalability, fault tolerance, and complexityUnderstand the distributed systems research upon which modern databases are builtPeek behind the scenes of major online services, and learn from their architectures Read more

Publisher ‏ : ‎ O'Reilly Media


Publication date ‏ : ‎ May 2, 2017


Edition ‏ : ‎ 1st


Language ‏ : ‎ English


Print length ‏ : ‎ 614 pages


ISBN-10 ‏ : ‎ 1449373321


ISBN-13 ‏ : ‎ 20


Item Weight ‏ : ‎ 2.1 pounds


Dimensions ‏ : ‎ 7 x 1.25 x 9.5 inches


Best Sellers Rank: #45,168 in Books (See Top 100 in Books) #2 in MySQL Guides #10 in Data Modeling & Design (Books) #56 in Computer Software (Books)


Frequently asked questions

If you place your order now, the estimated arrival date for this product is: Tuesday, Oct 13

Yes, absolutely! You may return this product for a full refund within 30 days of receiving it.

To initiate a return, please visit our Returns Center.

View our full returns policy here.

  • Klarna Financing
  • Affirm Pay in 4
  • Affirm Financing
  • Afterpay Financing
  • Zip Pay in 4
  • Financing through Apple Pay
  • Financing through Google Pay
Leasing options through Acima may also be available during checkout.

Learn more about financing & leasing here.

Top Amazon Reviews


  • Essential reading for anyone working on distributed systems in any capacity
Format: Paperback
Designing Data-Intensive Applications really exceeded my expectations. Even if you are experienced in this area this book will re-enforce things you know (or sort of know) and bring to light new ways of thinking about solving distributed systems and data problems. It will give you a solid understanding of how to choose the right tech for different use cases. The book really pulls you in with an intro that is more high level, but mentions problems and solutions that really anyone who has worked on these types of applications have either encountered or heard mention of. The promise it makes is to take these issues such as scalability, maintainability and durability and explain how to decide on the right solutions to these issues for the problems you are solving. It does an amazing job of that throughout the book. This book covers a lot, but at the same time it knows exactly when to go deep on a subject. Right when it seems like it may be going too deep on things like how different types of databases are implemented (SSTables, B-trees, etc.) or on comparing different consensus algorithms, it is quick to point out how and why those things are important to practical real-world problems and how understanding those things is actually vital to the success of a system. Along those same lines it is excellent at circling back to concepts introduced at prior points in the book. For example the book goes into how log based storage is used for some databases as their core way of storing data and for durability in other cases. Later in the book when getting into different message/eventing systems such as Kafka and ActiveMQ things swing back to how these systems utilize log based storage in similar ways. Even if you have prior knowledge or even have worked with these technologies, how and why they work and the pros and cons of each become crystal clear and really solidified. Same can be said of it's great explanations of things like ZooKeeper and why specific solutions like Kafka make use of it. This book is also amazing at shedding light on the fact that so little of what is out there is totally new, it attempts to go back as far as it can at times on where a certain technology's ideas originated (back to the 1800s at some points!). Bringing in this history really gives a lot of context around the original problems that were being solved, which in turn helps understanding pros and cons. One example is the way it goes through the history of batch processing systems and HDFS. The author starts with MapReduce and relating it to tech that was developed decades before. This really clarifies how we got from batch processing systems on proprietary hardware to things like MapReduce on commodity hardware thanks in part to HDFS, eventually to stream based processing. It also does great at explaining the pros and cons of each and when one might choose one technology over the other. That's really the theme of this book, teaching the reader how to compare and contrast different technologies for solving distributed systems and data problems. It teaches you to read between the lines on how certain technologies work so that you can identify the pros and cons early and without needing them to be spelled out by the authors of those technologies. When thinking about databases it teaches you to really consider the durability/scalability model and how things are no where near black and white between "consistent" vs "eventually consistent", these is a ton of nuance there and it goes deep on things like single vs multi leader vs leaderless, linearizability, total order broadcast, and different consensus algorithms. I could go on forever about this book. To name a few other things it touches on to get a good idea of the breadth here: networking (and networking faults), OLAP, OLTP, 2 phase locking, graph databases, 2 phase commit, data encoding, general fault tolerance, compatibility, message passing, everything I mentioned above, and the list goes on and on and on. I recommend anyone who does any kind of work with these systems takes the time to read this book. All 600ish pages are worth reading, and it's presented in an excellent, engaging way with real world practical examples for everything. ... show more
Reviewed in the United States on June 1, 2020 by Joey

  • A Must-Read for System Design and Distributed Systems
Format: Paperback
This is one of the best books on distributed systems and large-scale data architecture. It explains complex concepts in a clear, intuitive way while covering the principles behind building reliable, scalable, and maintainable systems. The writing is engaging, the examples are thoughtful, and the ideas remain highly relevant. Whether you're preparing for system design interviews or designing production systems, this is a book you'll come back to again and again. Highly recommended for software engineers and architects. ... show more
Reviewed in the United States on July 27, 2026 by Amazon Customer

  • A practical introduction to distributed systems
Format: Paperback
In today’s world, many of us have been tasked with building reliable, scalable services. Yet, more often than not, we rely on existing abstractions without fully understanding how the underlying systems work. Need a scalable database? Use MongoDB. Need a streaming service? Kafka is your go-to. While these tools get the job done, they often serve as crutches that prevent us from delving into the complexities of distributed systems. This book, Designing Data-Intensive Applications, is an eye-opener for anyone who has ever wondered about the internals of these services. It takes a deep dive into key concepts like consistency, exploring the critical differences between strong and weak consistency, and the trade-offs that come with each approach. For example, when a master node fails, how does a new master get elected? The book explains this process in depth, shedding light on the mechanics of fault tolerance. The book also provides clarity on how databases store and retrieve data efficiently. If you’ve ever come across PostgreSQL’s documentation and wondered, "What exactly is a B-tree?", this book will make it crystal clear. It also goes into the common gotchas when working with transactions. You might think that using transactions makes you safe from concurrency issues, but that’s not always the case. The book explains why this happens and offers practical advice on how to avoid race conditions. What this book isn’t: If you’re a practitioner building distributed systems from scratch and looking for in-depth explanations of algorithms like Raft, Paxos, or other low-level details, this book might not be what you’re looking for. It serves more as a high-level introduction to distributed systems rather than a deep dive into the specifics of consensus algorithms. For those looking for more detailed, foundational material on distributed systems, I’d recommend checking out Tanenbaum’s Distributed Systems. ... show more
Reviewed in the United States on September 17, 2025 by Roshan Patel

  • Must have book to understand data systems design philosophy
Format: Audiobook
Foundational knowledge so important nowadays
Reviewed in the United States on August 10, 2026 by Roman Y.

  • A Durable Cure for "Sort Bubble"
Format: Paperback
In Silicon Valley, "ability to code" is now the uber-metric to track. Starting from how engineers are interviewed, actual hands-on work (due to processes that overemphasizes "do" over "think, e.g., daily stand-ups require you to say what concrete thing you did yesterday), evaluation of work ("move fast and break things") to over-emphasizing on downstream "fixes" (prod-ops culture, 24*7 firefighting heroism) - the top echelon of technology gravitated towards things that it can see, feel, measure. What often gets neglected in this "code be all" culture is deep understanding of fundamental concepts, and how most newer "innovations" are indeed built on a handful time-honored principles. Nowhere else perhaps is this more prominent than in data space that up-levels libraries and frameworks as the conversation starter. That gets in the way of success. It is indeed impossible to model Cassandra "tables" without understanding - at least - quorum, compaction, log-merge data structure. Due to the way the present day solutions are built ("fits one use case perfectly well"), if these solutions are not implemented well to the particular domain, failure is just a release away. Mr Kleppmann does a great job of articulating the "systems" aspects of data engineering. He starts from a functional 4 lines code to build a database to the way how one can interpret and implement concurrency, serializability, isolation and linearizability (the latter for distributed systems). His book also has over 800 pointers to state of the art research as well as some of the computer science's classic papers. The book slows down its pace on the chapter on Distributed System and on the final one. A good editor could have trimmed about 120 pages and still retain most value one could get from the book. That said, if you ever worked on data systems, especially across paradigms (IMS -> RDBMS -> NoSQL -> Map-Reduce -> Spark -> Streaming -> Polyglot), this book is pretty much only resource out there to tie the "loose ends" and paint a coherent narrative. Highly recommended! ... show more
Reviewed in the United States on October 13, 2017 by Nilendu Misra

  • An exceptionally good review of the state of the art
Format: Paperback
It is really hard to overstate how comprehensively this book covers nearly everything that is currently known about building large, scalable, high performance, data centric applications. If every Kafka queueing, Cassandra clustering, Redis loving, Kinesis slinging, Map reducing, CAP theorem quoting systems engineer read this book, the world would actually be a better place. It really is that good. The front pages contain a quote from Alan Kay that I will summarize as "most people who write code for money ... have no idea where [their culture came from]." This book will learn you some of the culture you are missing! Every developer writing modern Internet facing application software, particularly in cloud computing environments, will run into the problems described here. Far too many of these developers will pick up a grab bag of half baked solutions from reading various Stack Overflow posts, blogs from better informed writers, and from hyped up claims made by the currently trendy "technologies." Many of these sources will obscure the fundamental nature of the underlying problems, and will lead said developers to overly naive designs, and provide a false sense of security. Such systems will even work pretty nicely for a while, but they will usually fail spectacularly when they are actually presented with component failures or high system load (or both at the same time, which is quite typical). This book talks about the underlying structure of the problems we all face when building contemporary distributed applications. It ties together all the foundational aspects of both distributed computing and data storage in a chorent manner. It teaches you how to think about the problem space by demonstrating where many popular and widely used software products fit. You're not going to learn about any one single product. Instead you will learn what you must know to evaluate as many of them as you want, learn which interactions between different components matter, and then make informed choices for your own design. This is not an academic text book, it is a working professional's guide to the field. It has all the references to the classic papers and textbooks that form the formal foundations of the subject, But it is so clearly written, and accessible, that you could go a very long way without needing to read any of them. ... show more
Reviewed in the United States on May 3, 2020 by Code Monkey

  • One of the best technical books I've ever read
Sometimes I think it's funny how hard it is for me to properly review a great book - even a technical one, where one would think reviewing comes easier. So, let's whip out the big guns right off the bat - this is probably the best technical book that I've ever read and it's very likely I'll be returning to it for a refresher from time to time. But what makes it so great, an inquisitive mind might ask? There wasn't a lot of practical value in it, at least not of the kind that would be instantly applicable. Same goes for theoretical knowledge: seeing the multitude of topics that were covered in its chapters, it's no wonder that none of said topics were explored in great detail; in fact, each of the topics has already racked up quite a bibliography over the years. For me, the value lies in the journey through various concepts and techniques used by databases in particular and distributed systems in general, and ultimately in a better understanding of said systems that came at the end of it. While none of the chapters dove very deeply into the said concepts or techniques, each of them were nevertheless explained in sufficient detail alongside the problems they were trying to solve. It's also worth noting that the amount of references that accompanies each chapter is simply staggering - blog posts, science papers, books, there's thousands of entries in total. Martin Kleppmann provided us with a fantastic, high-level navigational map through the many seas and lands of the databases and he gave us the tools to explore further should we so desire. I personally couldn't ask for more. ... show more
Reviewed in the United States on November 17, 2020 by FingolfinTEK

  • A flare on a battlefield
Imagine that your coding project is like being stuck on a battlefield at night, trying to cut your way through a maze of barbed wire. The average software book is like a flashlight: it illuminates the immediate problem and helps you figure out how to solve it. This book, in contrast, is like a flare shot high into the air. For a brief few moments, it illuminates the entire battlefield, and you can see your lines behind you, the positions of the enemy trenches and fortifications, and even roads, fields and forest in the distance. You're still going to need the flashlight for getting the job done, but getting perspective is invaluable for figuring out where you are and where you're going. If all you want to know is the minimum needed to do your job _today_, you probably won't like this book, because it covers too much territory to teach you the details of how to do any one thing. However if you want to understand how your current objective fits into the bigger landscape (and why), this book is one of the best overviews I've ever read, for any discipline. Kleppmann has a deep knowledge of the fundamentals and he writes in lucid, simple prose so that anyone can understand the concepts. There's a surprising amount of nitty-gritty detail about things like replication and sharding in distributed databases, and once you grasp the concepts, you'll be well-equipped to judge for yourself how any system fits your needs. Much of what one reads online about database software has the flavor of commercial advertising or semi-religous feuding among disciples of one system or another. So for me it was a real gift to have Kleppmann explain how technical details distingish data systems from each other, why the system designers made those choices, and what strengths and weaknesses result from them. I highly recommend the book. ... show more
Reviewed in the United States on May 13, 2021 by GenghisKhan

Can't find a product?

Find it on Amazon first, then paste the link below.
Checking for best price...